Long before a recruiter reads a word you wrote, a piece of software has already taken your resume apart and put it back together as rows in a database. That process is called resume parsing, and almost everything written about it is aimed at the people buying the software rather than the person whose career is being fed into it.
This is the other version. Not what parsing does for a recruiter, but what it does to your file: which fields come out clean, which ones silently disappear, and why the resume you were proudest of can be the one that parses worst.
What resume parsing actually is
A resume parser reads an unstructured document and converts it into structured fields. Your name, email address, phone number, each employer, each job title, the start and end date of every role, your degree, your institution, your skills. Indeed describes it as software that stores and analyses resume data automatically so it can be searched and filtered at volume.
The important part is the word convert. A resume is a designed document: it has a visual order that your eye follows. A database row has no visual order at all. Parsing is the step where the first becomes the second, and anything the parser cannot confidently place gets dropped rather than guessed at.
This matters more at large employers than small ones. Applicant tracking systems are standard infrastructure at the top of the market, where SHRM reports Workday is the leading choice among Fortune 500 companies. At a ten-person company someone may well open your PDF directly. At a large one, the searchable record created by the parser is, for practical purposes, your application.
What comes out the other side
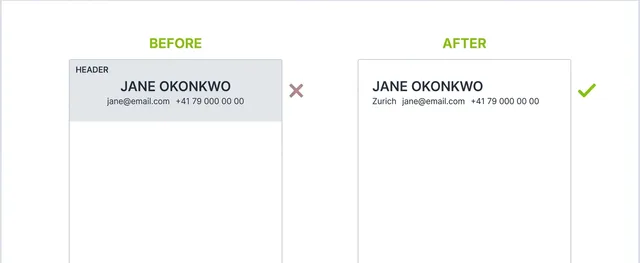
A parser is trying to fill a fixed set of slots. It looks for a contact block, a work history with employers and dates attached to titles, an education block, and a list of skills. Everything else in your document, including your beautiful summary paragraph, is usually stored as raw text that nobody searches.
That has a consequence worth sitting with. Recruiters do not read their database, they query it. They search for a job title, a skill, a location, a graduation year. If a field is empty, you are still in the system, but you have quietly stopped matching the searches that would have surfaced you. You do not get a rejection for this. You get silence, which is indistinguishable from every other kind of silence in a job search.